The GEO Study ChatGPT, by ELNIQ GEO and Queseo, shows why a single response is not enough to measure a brand’s visibility in AI search.
Study and data, freeReports in five languages, original data and charts.
Go to the download ↓If you ask ChatGPT for the best professionals in a field, you will probably get a list of names, specialities and arguments that sound quite convincing.
But what happens if you repeat exactly the same question? Do the same professionals appear again? Do they keep their position? And what if you use the OpenAI API instead of ChatGPT in the browser?
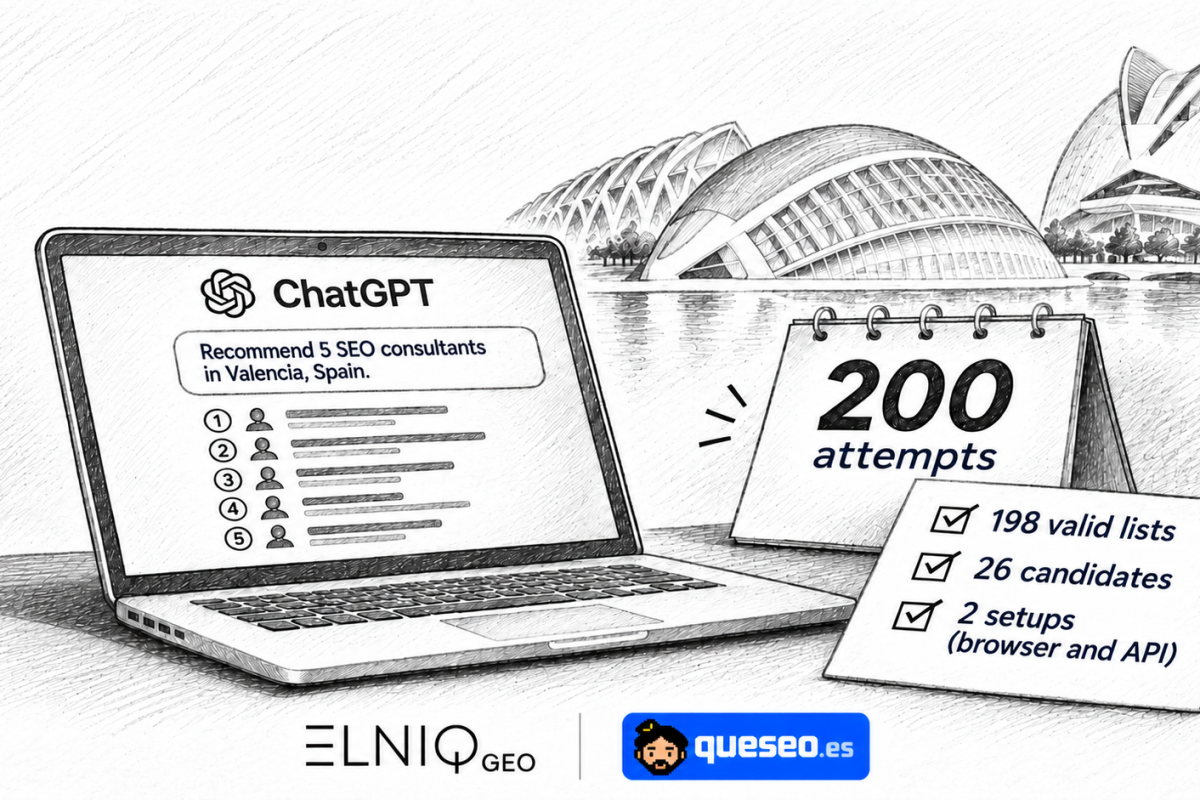
To explore these questions, we at ELNIQ GEO, together with Eric Jorge Seguí Parejo, SEO consultant (Queseo), ran an experiment on recommendations of SEO consultants in Valencia.
We made 200 attempts with the same question, in two different environments. We obtained 198 valid lists and analysed 990 recommendation slots.
The main result is clear: the lists change constantly, but behind that variation there are also patterns we can measure.
And this has important consequences for anyone trying to understand their visibility in ChatGPT.
| Finding | Observed result |
|---|---|
| The ordered list almost never repeats | 94 different lists in the browser and 95 in the API. |
| The two environments show different options | A list from each environment shares, on average, 1.77 of its five names. |
| Appearing and ranking first are different measures | Queseo is the most frequent brand in the API; Jesús Porres tops more lists. |
| A source is not a recommendation | ip10.es appears in 96 of 97 site records, yet fills no recommendation slot. |
| Few responses give a partial view | With 10 independent responses, the indicative margin is ±31 points. |
The experiment: one question, two environments
We used a simple query (in Spanish, as it was run):
Recomiéndame 5 consultores SEO en Valencia, España. Explica brevemente por qué recomiendas a cada uno.
“Recommend 5 SEO consultants in Valencia, Spain. Briefly explain why you recommend each one.”
We repeated it 100 times in free ChatGPT, from the browser and without logging in, and another 100 times through the OpenAI API, using the gpt-5.6-luna model with web search enabled.
The tests were run on 8 and 9 November 2026. Eric took care of the browser queries, while at ELNIQ we ran the tests with our GEO Lab API Tester tool.
Two browser attempts did not produce a complete list. The analysis is therefore based on 98 browser responses and 100 API responses.
| Condition | Browser | API |
|---|---|---|
| Environment | Free ChatGPT, not logged in | OpenAI API with web search |
| Model | Unknown | gpt-5.6-luna |
| Attempts / valid lists | 100 / 98 (attempts 28 and 44 did not finish) | 100 / 100 |
| Dates | 8–9 November 2026 | 8–9 November 2026 |
To count the results, we unified the different ways of referring to the same person or brand. For example, “Eric Jorge Seguí Parejo” and “Queseo” were counted as a single candidate.
We did not modify the participants’ websites or carry out any intervention aimed at improving their visibility. Our goal was to observe and measure how the recommendations behave.
We do not know which model answered in the browser. In addition, search and presentation conditions differed between the two environments. For that reason, the differences observed cannot be attributed solely to using the browser or the API.
Video presentation of the study
In this video we explain the main results of the experiment.
This video, all the study materials and a description of our work and the results we obtained are also available on the website of SEO consultant Queseo (Eric Jorge Seguí Parejo).
1. Almost every response gives a different list
This was the first result that caught our attention.
Of the 98 valid browser responses, we found 94 different lists when taking into account both the names and their order. In the API, we obtained 95 different lists out of 100.
If we ignore positions and look only at which five candidates appear together, the variability decreases but is still considerable: 68 different combinations in the browser and 67 in the API.
To understand how similar the responses are, we compared the lists with each other.
Two browser responses shared, on average, 2.30 names out of five. In the API, the average was 2.62. When comparing a browser list with an API list, the overlap dropped to 1.77 names.
Chart 1Names shared by two lists (out of 5)
Average over 4,753 browser pairs, 4,950 API pairs and 9,800 cross pairs.
Across the 9,800 possible comparisons between browser lists and API lists, there were ten pairs with the same five candidates, although in a different order. None matched exactly in both names and positions.
This means a single response can show only a very limited part of the set of professionals ChatGPT may recommend.
If your brand appears in one query, you still do not know whether that is a frequent presence or an exceptional appearance. And if it does not appear, you cannot conclude that ChatGPT never recommends it.
A response is an observation, not a complete measurement of visibility.
2. Visibility changes depending on the environment
Another especially relevant result was the difference between ChatGPT in the browser and the API.
Some professionals appeared very frequently in one environment and barely at all in the other.
For example, Enrique Tejedo was recommended in 77 of the 98 browser lists, but in only one of the 100 API responses. Queseo showed the opposite behaviour: it appeared in 37 browser lists and in 87 API lists. Other cases were less extreme. Alex Figueiras appeared in 54 browser lists and in 62 API lists.
Chart 2Presence in the lists, by environment (%)
Percentage of valid lists in which each consultant appears (98 browser, 100 API). Six of the 26 candidates are shown; the rest are in the report.
We are not saying that one environment recommends better than the other. Nor can we claim that these results would repeat with another model, on another day or with a different configuration.
What our sample does show is that results from one API configuration should not automatically be presented as equivalent to what a ChatGPT user sees.
This directly affects tools that monitor AI visibility. When a platform shows a presence percentage or an average position, it is essential to know what it is measuring: which model it uses, how it runs the queries, whether it includes web search and under what conditions it obtains the responses.
Without that information, interpreting the results can be misleading.
3. Appearing often does not mean ranking first
In traditional SEO we are used to talking about positions. In ChatGPT recommendations, however, position is only part of the problem.
A professional can appear in many lists, but almost always at the end. Another can appear less often and, when they do, take first place.
Alex Figueiras was recommended with a relatively similar frequency in both environments: 54 times in the browser and 62 in the API. However, he topped 25 browser lists and only two API lists.
In the API responses, Queseo was the brand with the highest presence, with 87 appearances. But Jesús Porres was the one who took first place most often: 50 times versus Queseo’s 28.
| Consultant | Browser: 1st | Browser: top 3 | API: 1st | API: top 3 |
|---|---|---|---|---|
| Enrique Tejedo | 26 | 66 | 1 | 1 |
| Cerdá (Seomar) | 24 | 45 | 6 | 29 |
| Alex Figueiras | 25 | 39 | 2 | 27 |
| Jesús Porres | 10 | 31 | 50 | 74 |
| Queseo | 0 | 10 | 28 | 77 |
| Rocío Santamaría | 0 | 17 | 0 | 27 |
Number of lists in which the consultant is first or among the top three (browser: 98 lists; API: 100).
Therefore, to measure visibility it is worth separating at least three indicators:
- Presence: in what percentage of responses the brand appears.
- Position: what place it takes when it appears.
- Link: whether the response includes an address that lets users visit its website.
None of these indicators, on its own, allows us to judge the professional quality of the candidates. Nor do they necessarily represent traffic or conversions.
4. Appearing in the sources is not the same as being recommended
A particularly interesting part of our analysis was the relationship between the recorded sources, the links and the recommended professionals.
The most illustrative example was IP10, a directory that includes a comparison of SEO consultants in Valencia.
The domain ip10.es appeared in 96 of the 97 site records kept from the browser. Its comparison page appeared in all 97 page records, and the source label “IP10” was present in 68 of the 98 visible texts. However, IP10 did not occupy any of the 990 recommendation slots analysed.
This case helps us distinguish four different situations: a page appearing in the records associated with a response, being cited as a source, receiving a direct link, and a brand being recommended as a provider. They are not interchangeable indicators.
Nor should we assume that a domain’s presence in a record shows that its content was read before the candidates were selected. The data we kept do not allow us to fully reconstruct that process.
For GEO analysis, this distinction is fundamental: the visibility of a source and the visibility of a brand as a recommended option are related but different phenomena.
5. How many responses do we need to measure visibility?
If a single response is not enough, the next question is unavoidable: how many should we collect?
In the 198 lists of our experiment we identified 26 different candidates. In the browser, a selection of three lists found an average of 9.4 distinct candidates. With ten lists, the figure rose to 14.2. With twenty, to 16.4.
Chart 3Distinct candidates as more lists are reviewed
Number of lists reviewed →
Average number of distinct candidates in a random selection of k lists, computed on the saved responses (26 candidates in total). Browser: 5.0 / 9.4 / 14.2 / 16.4 with 1 / 3 / 10 / 20 lists. API: 5.0 / 8.9 / 13.2 / 15.4. It describes the diversity of our sample; it does not predict future names.
These figures are computed on the saved responses and describe the diversity of our sample. They do not predict how many new names will appear in future queries.
There is another problem: statistical uncertainty.
As a theoretical reference, if a brand appears in roughly 50% of responses, a sample of ten independent observations would have an indicative margin of ±31 percentage points at 95%. With a hundred responses, that margin would shrink to approximately ±9.8 points. To get close to ±5 points, around 385 observations would be needed, under the same statistical assumptions.
Chart 4Indicative margin for a true frequency of 50%
95% interval for a sample of n independent responses. This is a theoretical calculation, not a property guaranteed by ChatGPT.
These margins are not guaranteed by ChatGPT. The calculation assumes independent responses and a relatively stable frequency, conditions that our experiment does not demonstrate.
There is therefore no universal number of queries that guarantees an accurate measurement. What we can say is that small samples are very sensitive to variation, and that any presence percentage should be reported together with the number of valid responses used to calculate it.
6. What ChatGPT says about a brand also matters
So far we have talked about names, positions and links. But a recommendation has another important component: the description the user receives.
When someone asks about an SEO consultant, ChatGPT does not just list professionals. It explains what each one does, what their specialities are and what kinds of projects they might suit.
In our study we observed that some associations were repeated. Queseo appeared related to website migrations in all of its analysed descriptions, in both the browser and the API. Jesús Porres was frequently associated with local businesses and professional services, while Rocío Santamaría appeared linked to artificial intelligence, GEO and generative search.
This leads to a question that presence metrics cannot answer on their own:
Is ChatGPT recommending your brand for the services and needs you actually want to be positioned for?
Appearing as a local SEO specialist is not the same as appearing as an expert in technical migrations or e-commerce. For a company, understanding these associations can be as relevant as counting how many times its name appears.
But there is an important caution: the fact that ChatGPT attributes a speciality or cites a figure for experience does not mean that the claim has been independently verified.
7. When the listing, the link and the identity do not match
The study also detected discrepancies between the recommended names, the linked sites and some business listings.
For example, certain listings associated with Jamil Mansilla included the domain cristaleriasmansilla.com, while the link in his main description pointed to jamilmansilla.com. In other cases, the listings linked to Rocío Santamaría showed a different domain and different review figures from those in the text of the recommendation.
These examples do not show by themselves where the errors originated: they could be related to how listings were selected, how they were presented or how the data were extracted. But they reveal a risk worth attention.
A brand can be recommended and, at the same time, accompanied by information that needs to be checked. That is why, when analysing AI visibility, it is also worth reviewing the consistency of the names, domains, listings and data attributed to each entity.
In addition, in the browser responses we found business listings recorded in 40 of the 98 cases and maps visible in 32. The distribution of candidates varied between responses with and without listings, although our experiment does not allow us to establish a causal relationship.
What this all means for GEO measurement
Our experiment does not offer a formula to get ChatGPT to recommend a brand. Nor does it aim to establish who the best SEO consultant in Valencia is.
What it offers is an empirical basis for thinking about how we should measure visibility in generative search systems. From the results, we consider three principles especially important.
- Measure repeatedly and document the conditions. A sample needs to include the exact question, the date, the environment, the model when known and the number of valid responses. Without that context, comparing percentages can lead to wrong conclusions.
- Separate the different dimensions of visibility. Presence, position, links, sources, maps and descriptions provide different information. They should not automatically be reduced to a single score.
- Observe changes over time. Our experiment was run over a single night and with a single question about one specific sector. To understand whether the patterns hold, we need to repeat the tests on other dates and under comparable conditions.
This is one of the lines of research we want to keep developing at GEO Lab: tools and methodologies that help observe AI search in a reproducible, transparent and data-based way.
A joint study by ELNIQ GEO and Queseo


Disclosure: Queseo is also one of the brands recommended in the responses analysed. The same counting criterion is applied to all candidates.
The analysis is based on data obtained on 8 and 9 November 2026. The full report includes the tables for the 26 candidates, the comparisons between responses, the link records, the source analyses and the methodological details. It is written in Spanish.
Open study and data
Download the research
Full report, methodology and original research data. Free access.
What is in the archive?
- Estudio_GEO_ChatGPT_ELNIQ_Queseo (ES, EN, VA, RU, UK).pdf The final study as a PDF, 31 pages, in five languages: Spanish, English, Valencian, Russian and Ukrainian.
- datos-en-bruto-de-consultas.zip The two original Excel files with the responses: one from the browser and one from the API.
- Estudio_Claude_GEO_ELNIQ_Queseo.zip A previous analysis of the same data made with Claude: 3 PDFs, 3 Excel files and 6 charts (PNG).
- Estudio_GEO_ChatGPT_Valencia.zip A previous analysis of the same data made with ChatGPT: one PDF and 12 charts and tables (PNG).
Follow the research at GEO Lab
Tools and methodologies to observe AI search in a reproducible, transparent and data-based way.
References
- Aggarwal et al. (2024). GEO: Generative Engine Optimization. arxiv.org/abs/2311.09735v3
- Liu, Zhang & Liang (2023). aclanthology.org/2023.findings-emnlp.467
- OpenAI. Web search, sources. developers.openai.com
- NIST/SEMATECH e-Handbook of Statistical Methods. itl.nist.gov
Research: ELNIQ GEO × Queseo
Authors: Nina S. Dzhezher and Eric Jorge Seguí Parejo
Data collection: 8–9 November 2026 · Report: 11 November 2026
More information: ELNIQ GEO · Queseo
Study and data, freeReports in five languages, original data and charts.
Go to the download ↓